FT-8 Project?

Simon Brown • September 13, 2026

Project for 2027?

Love it or hate it, FT-8 is here to stay. I use WSJT-X to monitor 2m and sometimes 70cms. As a software developer, it's always rewarding to use one's own software. So I just asked ChatGPT whether it (he, she, they) even knew about FT-8. The response was amazing.


So, this could be the start of a project which is also used for EME and meteor scatter modes. Read on dear reader, read on.
Question (Me)

I've been working with ChatGPT to optimise the digital signal processing (DSP) in my SDR Television software, so ChatGPT and myself have history, ChatGPT knows me well.


I asked ChatGPT "Do you know what FT-8 is? Do you think we could write a better decoder?". That's all I asked.


Reply (ChatGPT)

ChatGPT immediately replied!


Yes — very familiar with FT8, and yes, I think we could build a substantially better decoder, particularly if we approach it as a DSP/SDR problem rather than simply reimplementing WSJT-X.


FT8 is actually a very interesting fit for the sort of work we've been doing with your DVB-S2 decoder.

The current FT8 waveform is:

  • 15-second receive/transmit period
  • 79 symbols
  • 8-FSK
  • 6.25 baud
  • 6.25 Hz tone spacing
  • 50 Hz occupied bandwidth
  • three 7×7 Costas sync blocks
  • 174 transmitted coded bits
  • 77-bit payload + 14-bit CRC
  • LDPC(174,91)
  • Gray-coded 3-bit symbols


The really interesting part is that the LDPC decoder isn't necessarily where the biggest gains are. The front end and candidate generation are extremely important.


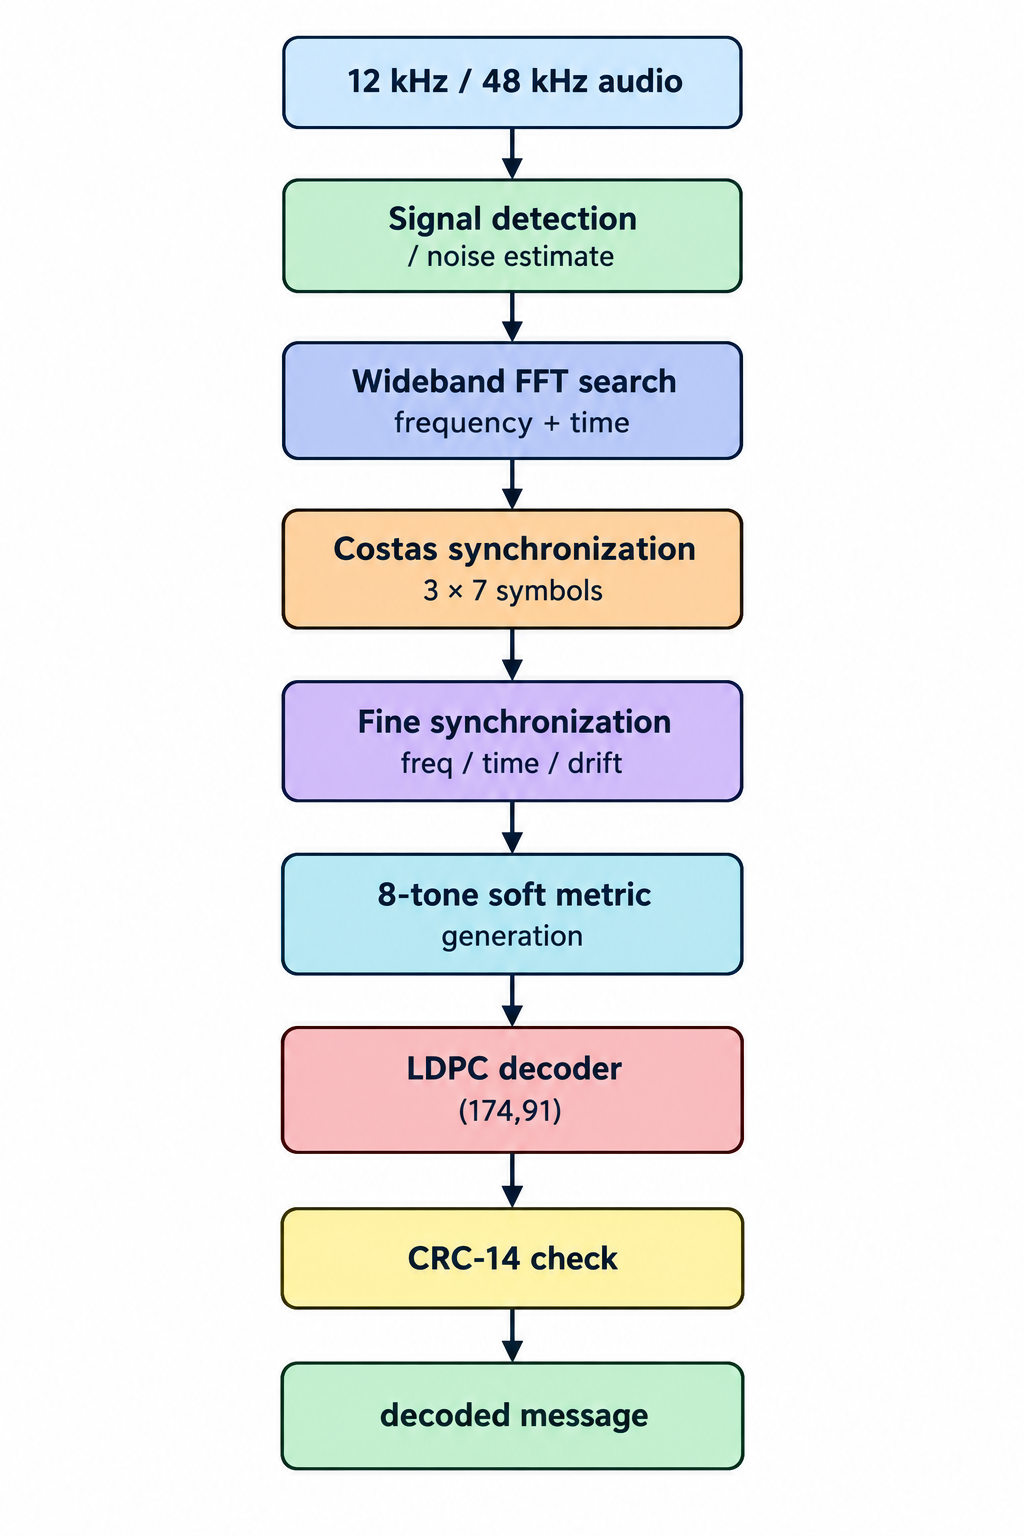
I'd build it as a multi-stage decoder, something along these lines:
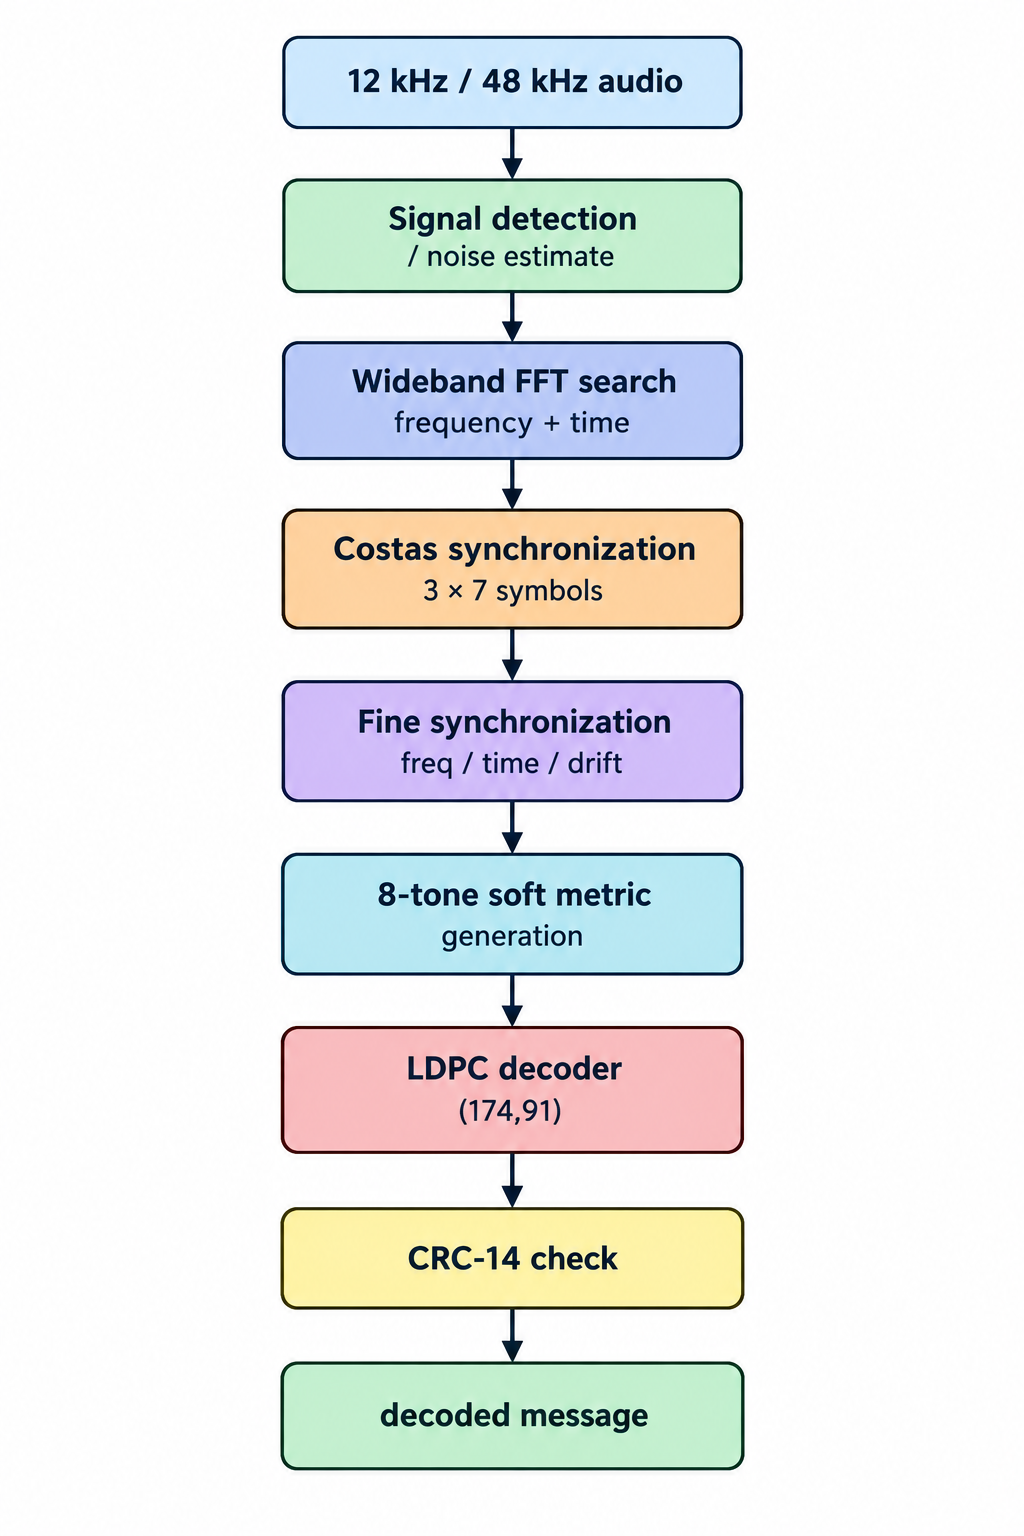

And then we could add the really powerful stuff:


1. Much better signal detection

Rather than simply looking for obvious FT8 traces in an FFT, I'd exploit the known Costas structure.


The three Costas blocks are known completely, so we effectively have a matched-filter/reference-correlation problem.

That lets us search for:

  • frequency,
  • fractional symbol timing,
  • frequency drift,
  • signal amplitude,
  • phase,
  • possibly time offset

simultaneously.


This is very similar philosophically to what we've been doing with your DVB-S2 SOF/PLHEADER detector.


2. Proper soft 8-FSK metrics

This is where I think we could make a significant improvement.

For every data symbol I'd calculate something like:

E0 E1 E2 E3 E4 E5 E6 E7

and convert those eight tone energies into soft bit LLRs.

Because each tone represents three Gray-coded bits, we can calculate the exact bit likelihood:

  • LLR(bit0)
  • LLR(bit1)
  • LLR(bit2)


rather than making a hard decision on the strongest tone. That gives the LDPC decoder substantially better information.

This is analogous to the lesson we found with your DVB-S2 QPSK decoder: the quality and scaling of the soft information going into LDPC can matter enormously.


3. Better LDPC decoding

FT8's code is LDPC(174,91), with the 91 bits consisting of the 77-bit message plus the CRC.

I'd initially implement:

  • normalized/offset min-sum,
  • sum-product,
  • layered scheduling if applicable,
  • adaptive damping,
  • early termination,
  • CRC-assisted termination.


But I'd also investigate OSD / ordered-statistics decoding as a second-stage decoder. That's particularly interesting for FT8 because the block is tiny. Some modern implementations already experiment with BP, OSD and a-priori-assisted decoding.


4. A-priori decoding

This is probably one of the biggest opportunities.

Suppose we know:

CQ G4ABC IO91


or we're in the middle of a QSO and already know one callsign. We don't have to treat all 77 payload bits as completely unknown. We can inject known information into the LDPC decoder. WSJT-X already uses several AP decoding strategies, including known callsigns and known message structures. But we could make this considerably more systematic.


For example:

5. Multi-signal decoding

This is where I'd really like to push it.

Imagine:
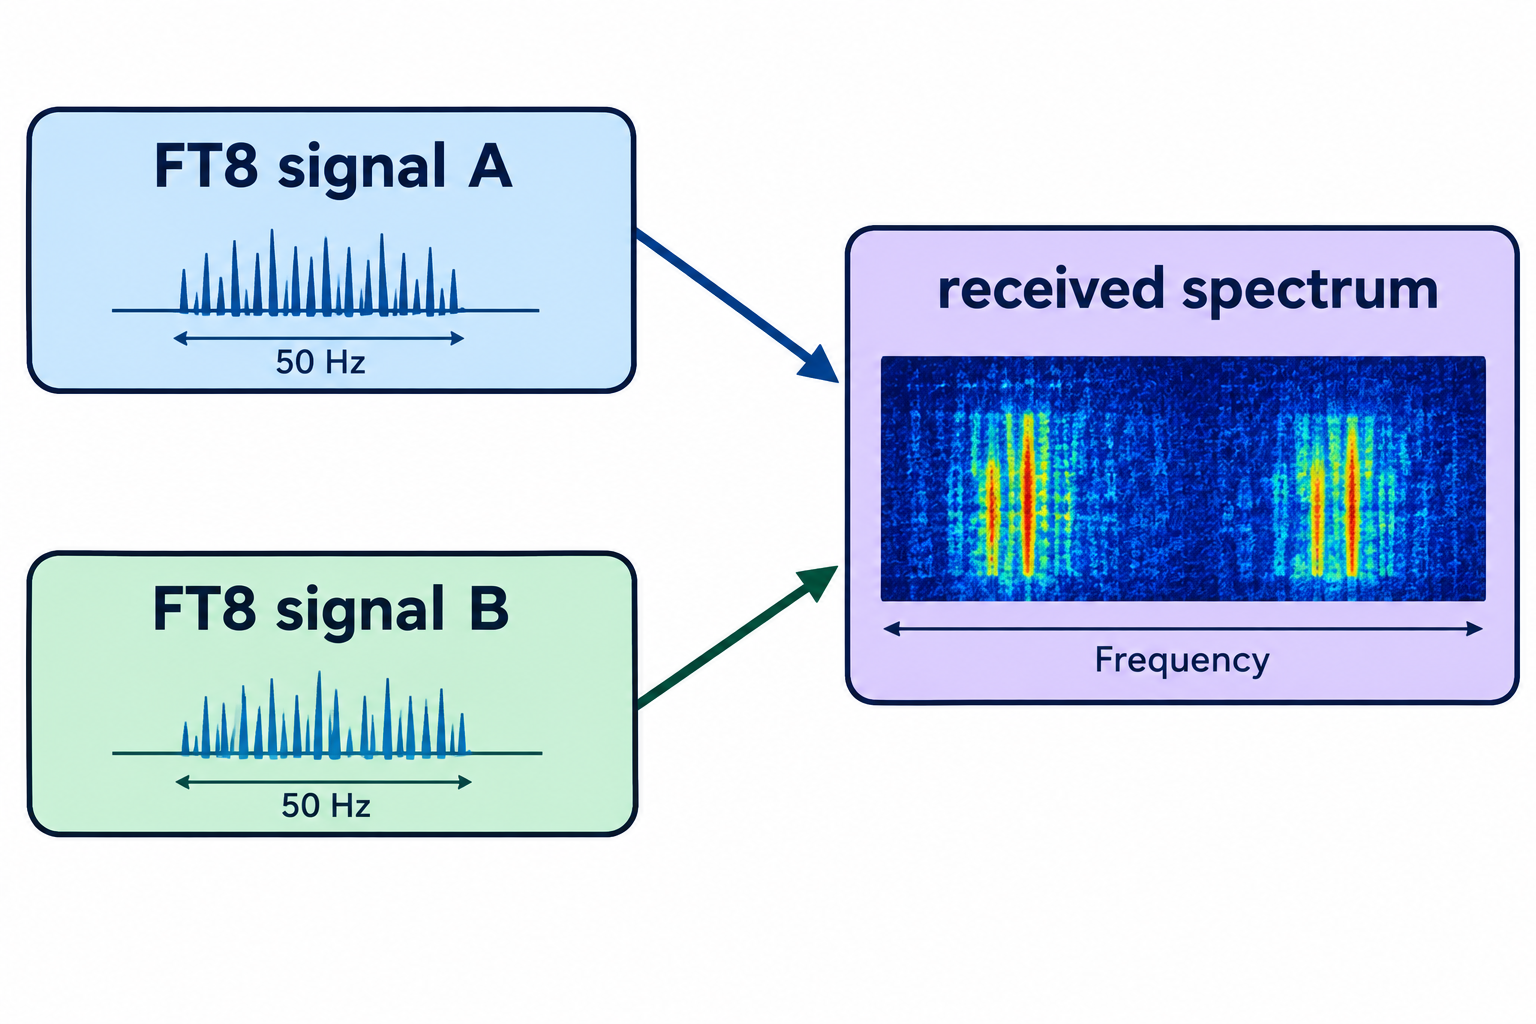

We decode A.

Once A is known, we know exactly what waveform A should have produced.

So:
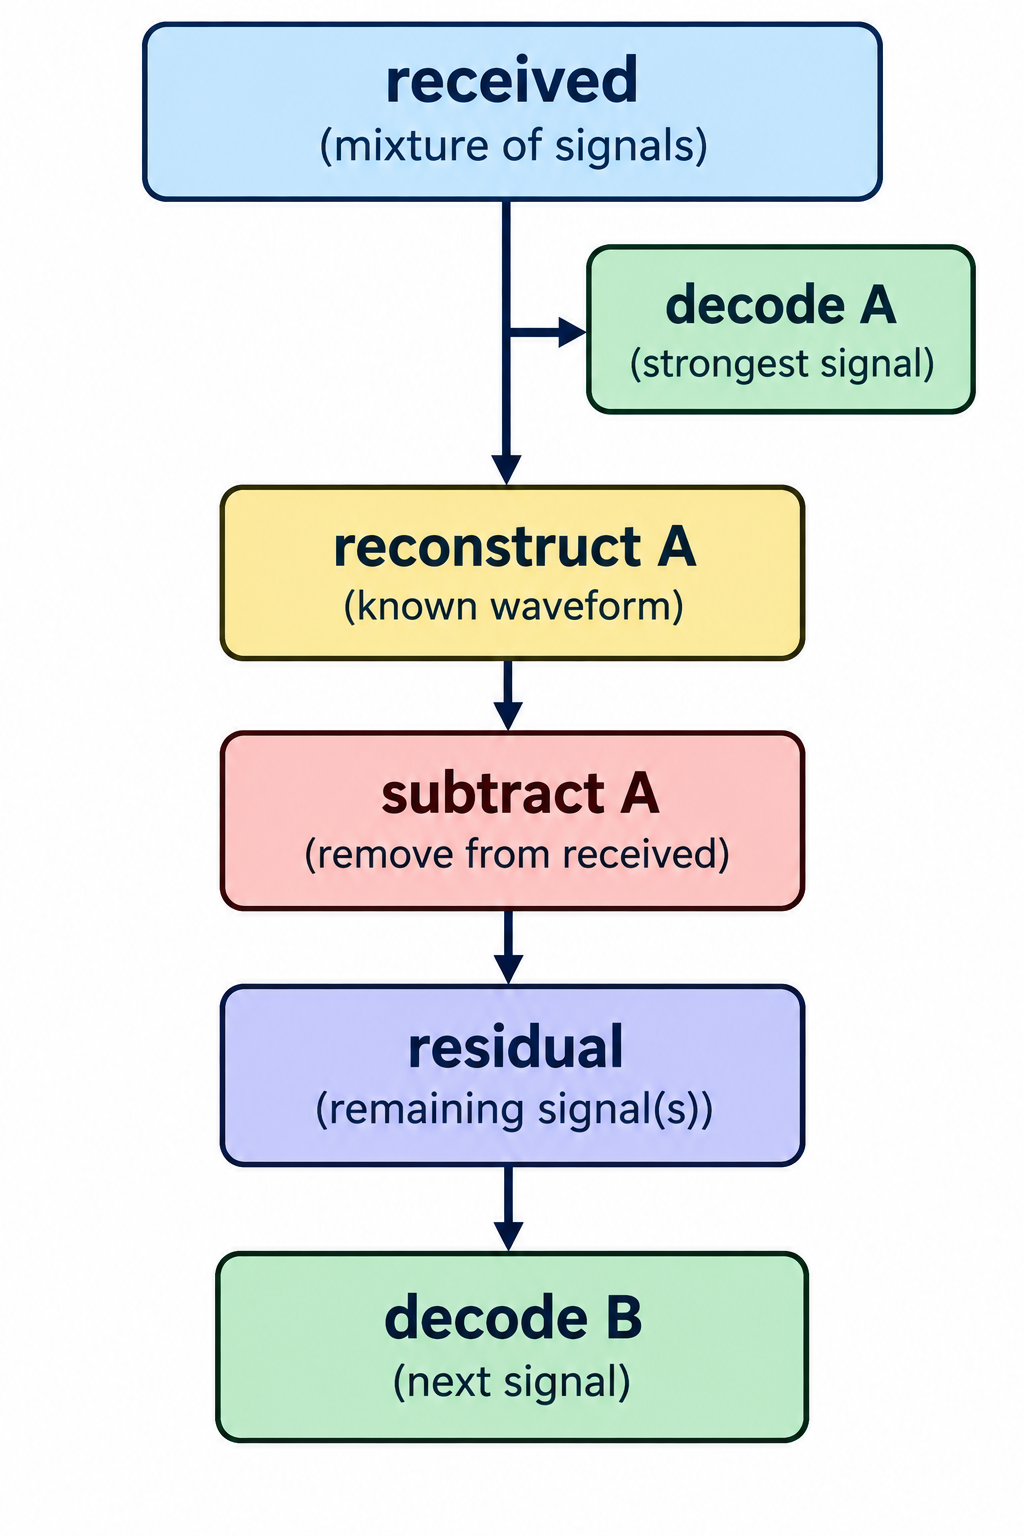

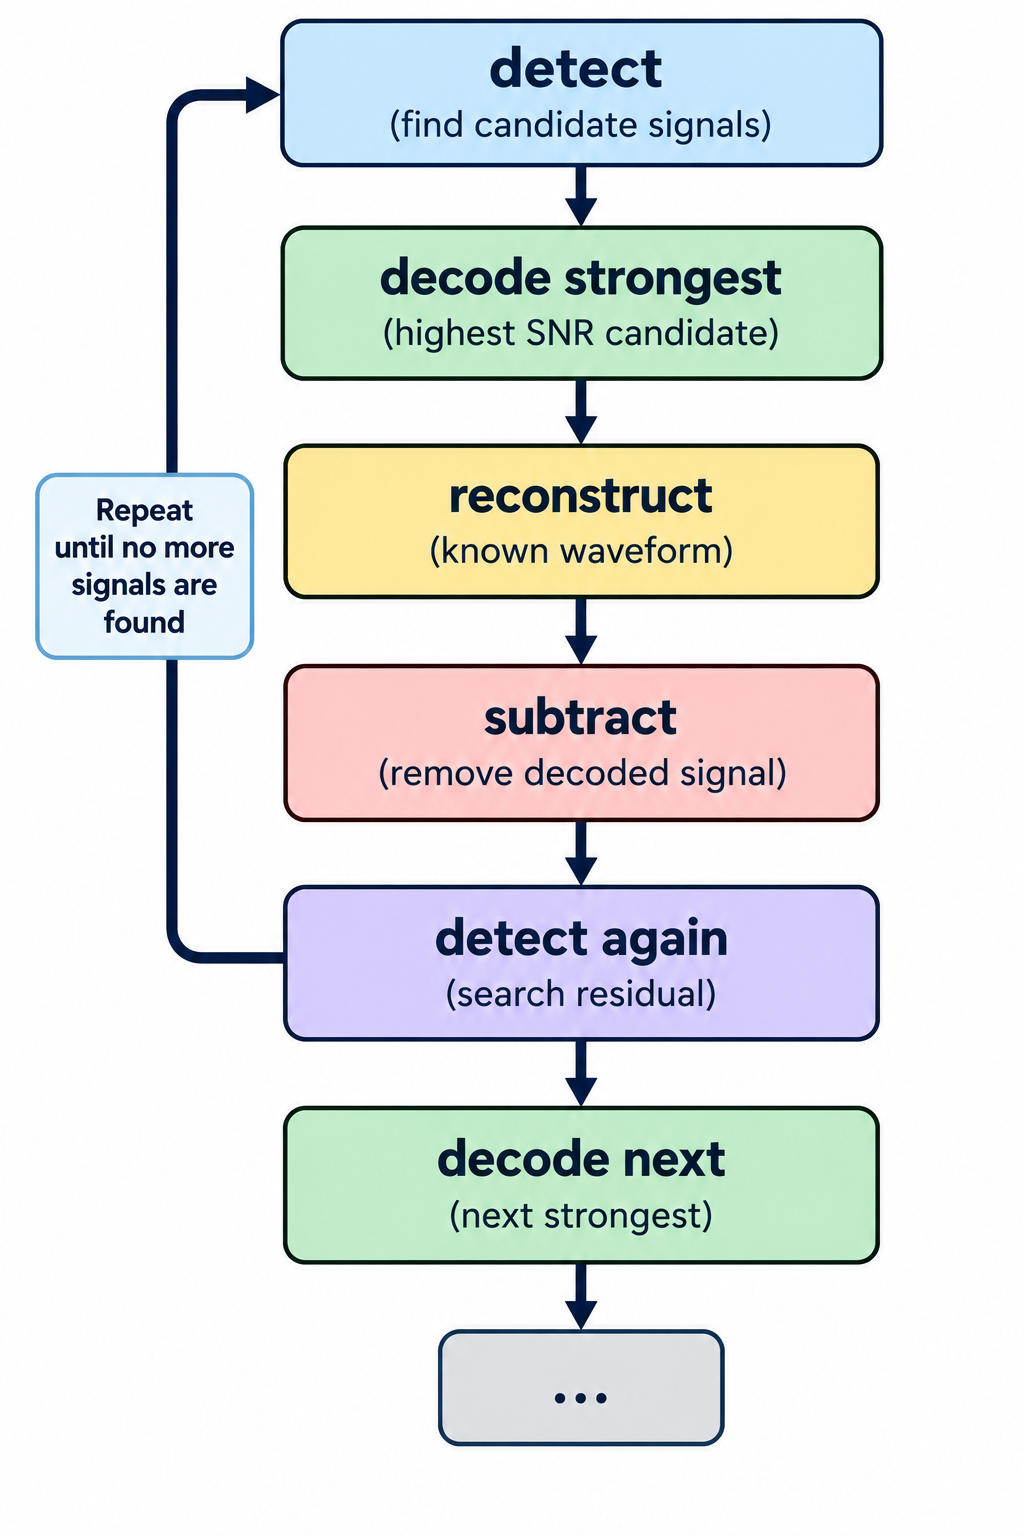
That can potentially expose signals that were completely buried underneath stronger FT8 transmissions. The original WSJT-X development notes explicitly contemplated signal subtraction and two-pass decoding.


I'd go further and make it iterative:

6. Frequency drift estimation

For HF FT8, a signal isn't necessarily sitting at one perfectly constant frequency.

We could estimate:

f(t) = f0 + f1*t + f2*t²


using the three Costas sequences. Then compensate the entire signal before extracting the data. That should help considerably with marginal signals and drifting oscillators.


And there's a particularly interesting experiment I'd like to do. Rather than immediately trying to beat WSJT-X, I'd build a reference-quality C++17 decoder and compare it against WSJT-X under controlled conditions.


For example:
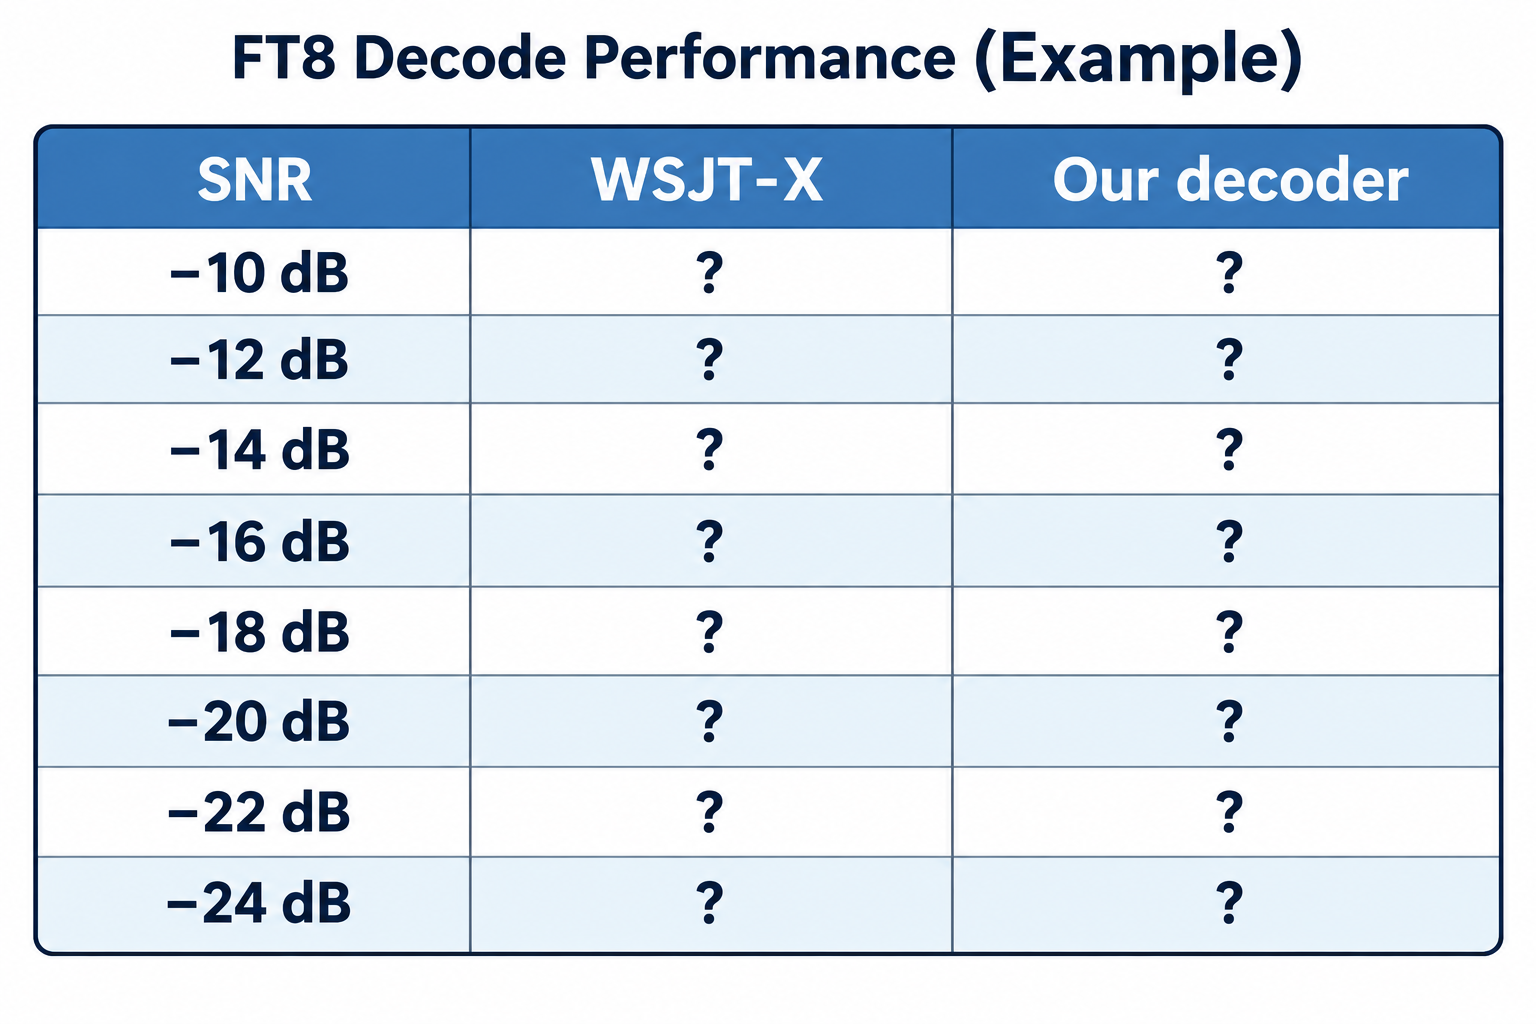

Generate thousands of known FT8 messages at each SNR, with controlled:

  • frequency offset
  • timing offset
  • frequency drift
  • AWGN
  • fading
  • adjacent signals
  • overlapping signals

and measure actual decode probability.


That would let us identify where the extra dB are coming from, rather than just saying "it decodes better".

FT8 is already capable of roughly −20 dB-class decoding under suitable conditions, with AP decoding providing additional sensitivity. And I think your existing DSP experience would transfer extremely well.


In particular, the things we've learned with your DVB-S2 work:

soft metrics → synchronization → noise estimation → LLR scaling → iterative decoding

are almost exactly the areas I'd concentrate on here.


I would not start by copying the WSJT-X decoder line-for-line.


I'd start with a clean C++17 implementation:

  • Ft8Decoder,
  • Ft8Synchronizer,
  • Ft8Detector,
  • Ft8SoftDemodulator,
  • Ft8Ldpc,
  • Ft8Message


with AVX2 where it actually helps.


Then we can benchmark each stage independently.


If you're interested, I think the first thing to build should be the FT8 soft demodulator + Costas synchronizer, because that will tell us whether there are meaningful gains available before we spend time on the LDPC side.
By Simon Brown • October 24, 2026
SDR Television v1.1.7 October 26th, 2026, Important bug fix and enhanced user interface. I've been using ChatGPT to help with both DSP and user interface design. Here we see the result of interface design. Receiver Finally found the cause of a bad memory leak. Every time User Interface Added an Octave Spectrum display, this is selected on the Receive and Transmit displays from the main dropdown, sub-menu "Audio Display..." as shown below. Added a new Style, SDR Television - Modern. Select the style from the Style dropdown in the top right-hand corner of the main display. Downloads are at the bottom of this page.
By Simon Brown • October 9, 2026
Introduction During September and October 2026 new noise blankers have been implemented to improve what was a weak part of the SDR Console signal processing chain. Using the knowledge of ChatGPT, this exercise took only five days and the result is shown below. These noise blankers will be available sometime in October 2026. Impulse Noise A noise blanker should remove Impulsive interference such as electrical switching noise, electric-fence pulses, ignition interference and short static crashes The screenshot below shows the new wideband noise blanker in action. The top half of the main waterfall shows the noise created by an electric fence, The bottom half shows the noise removed by the new wideband noise blanker.
By Simon Brown • October 9, 2026
RadioClear AI – A New Approach to Speech Noise Reduction Improving Weak Signal Reception One of the biggest challenges when listening to weak radio signals is separating speech from background noise. As signals become weaker, the noise can overwhelm the speech, making conversations difficult or sometimes impossible to understand. Conventional noise reduction has been available in software-defined radios for many years. Most systems analyse the received audio, estimate which frequencies contain noise, and reduce their amplitude. This can work very well, but there is always a compromise. Too little suppression leaves distracting background noise, while too much can make speech sound metallic, watery or unnatural. Important speech information may disappear along with the noise. For some time, I have wanted to develop a better approach for SDR Console, particularly for weak SSB reception. The objective was not simply to produce quieter audio, but to improve intelligibility while preserving the natural characteristics of the speaker's voice. The result is RadioClear AI , a new noise-reduction system combining adaptive digital signal processing with a recurrent neural network and complex temporal filtering. Comparison With RNNoise RadioClear AI and RNNoise both use neural networks to improve speech intelligibility by reducing unwanted background noise, but they employ different approaches. RNNoise is a well-established, computationally efficient solution that combines traditional signal processing with recurrent neural networks to estimate frequency-dependent suppression gains. It performs well across a variety of speech applications and has the advantage of being lightweight and widely tested. RadioClear AI has been developed specifically with radio communications in mind, particularly weak SSB signals affected by receiver noise. It combines adaptive noise estimation and speech-aware spectral processing with a recurrent neural network that generates complex temporal filter coefficients. Unlike conventional gain-based suppression, this approach uses information from consecutive audio frames to adjust both the amplitude and phase of the enhanced signal. Both approaches have strengths, and their relative performance depends on the type of interference, signal conditions and training material. RNNoise benefits from its maturity, efficiency and general-purpose design, while RadioClear offers a more specialised processing architecture tailored to weak radio reception. In initial listening tests, RadioClear AI has produced encouraging results, with cleaner background noise and natural-sounding speech compared with RNNoise on the signals tested. However, these observations are subjective, and controlled comparisons across a wider range of recordings would be needed to establish a consistent performance advantage. Further improvements to RadioClear's training data are planned, particularly using cleaner speech recordings and a greater variety of speakers and receiver noise conditions. Combining Traditional DSP with Artificial Intelligence Rather than relying entirely on artificial intelligence, RadioClear AI uses two complementary processing stages. The first stage is based on conventional digital signal processing. It continuously estimates the background noise and analyses the incoming audio to identify frequencies likely to contain speech. It also examines harmonic relationships, which are particularly important for voiced speech. This information is used by an adaptive spectral suppressor to reduce background noise while protecting important speech components. The result is an initial noise-reduced signal that provides a stable foundation for the neural network. This arrangement has an important advantage. The neural network does not need to learn everything about noise estimation and suppression from scratch. Instead, it receives a partially cleaned signal together with detailed information about the speech and noise characteristics. The neural network can then concentrate on improving the result. Looking Beyond Individual Audio Frames One of the limitations of conventional spectral noise reduction is that it generally operates by adjusting the amplitude of individual frequency components. However, speech is not a collection of unrelated frequencies. It is a continuously evolving signal with strong relationships between consecutive moments in time. RadioClear AI takes advantage of this. The incoming audio is divided into overlapping frames, and each frame is converted into a frequency-domain representation using a Fast Fourier Transform (FFT). The neural network receives 400 features describing the signal across 40 frequency bands. These include information about signal power, estimated noise, signal-to-noise ratio, speech probability, harmonic content and the relationships between consecutive complex spectra. At the heart of the system are two Gated Recurrent Unit (GRU) layers. Unlike a simple feed-forward neural network, a GRU maintains information about previous frames, allowing the system to recognise how speech changes over time. This temporal information is particularly valuable when the speech is partially obscured by noise. Complex Temporal Filtering The most significant difference between RadioClear AI and a conventional neural noise reducer is the way the network processes the audio. Many neural noise-reduction systems generate a set of gains that are applied to individual frequency bins. Although effective, this approach primarily controls amplitude. RadioClear AI goes further by generating complex-valued filter coefficients . For each frequency bin, the system combines information from the current audio frame and the previous two frames. The neural network determines how these spectra should be combined to produce the enhanced signal. Because the coefficients are complex, the system can modify both amplitude and phase. It can also exploit the relationships between consecutive frames rather than treating each frame independently. This gives the network considerably more flexibility than a conventional spectral gain mask. The neural network produces coefficients for 40 frequency bands, which are interpolated across the 257 FFT frequency bins. A three-tap complex temporal filter then generates the enhanced spectrum, which is converted back into audio. The complete process operates continuously in real time. Training the Neural Network The neural network is trained offline using examples of speech mixed with receiver noise. During training, the system is provided with both the noisy signal and the corresponding clean speech. It learns to generate complex filter coefficients that make the processed spectrum resemble the clean reference as closely as possible. An important development decision was to train the network against the actual reconstructed complex spectrum , rather than simply asking it to reproduce a set of ideal filter coefficients. This means the training process directly rewards improvements in the enhanced signal. The current network contains approximately 568,000 parameters and was trained using speech mixed with real receiver noise at signal-to-noise ratios ranging from +15 dB to −10 dB. The training and evaluation process showed substantial reductions in complex spectral error compared with the initial deterministic noise-reduction stage. The improvements were particularly encouraging at the lowest signal-to-noise ratios, where additional noise reduction is most valuable. Of course, mathematical measurements are only part of the story. A lower spectral error does not automatically guarantee better-sounding speech, so listening tests remain essential. Real-Time Processing and Listening Results The neural network was originally developed and trained using Python and PyTorch. The complete inference engine was then implemented in C++ for integration into SDR Console. To ensure that the C++ implementation behaved correctly, its results were compared directly with the Python reference. This included the recurrent network, complex coefficient generation, frequency interpolation and final spectral filtering. The results agreed to floating-point precision, giving confidence that the real-time implementation reproduces the trained model accurately. Initial listening tests have been very encouraging. On weak SSB signals, RadioClear AI produces natural-sounding speech with substantial background-noise reduction. In my own listening comparisons, the results have been noticeably better than RNNoise, particularly in preserving speech quality while reducing unwanted noise. An additional aggressiveness control has also proved useful, allowing stronger suppression of residual noise where desired. As always, the best setting depends on the received signal. Maximum noise reduction is not necessarily the same as maximum intelligibility, so the listener retains control over the amount of processing applied. What Comes Next? Although the current results are very promising, development is far from finished. One area where I expect further improvements is the training material. The first model was trained using a relatively small amount of speech, and the supposedly clean reference recording contained a little background noise. This is not ideal. If noise is present in the clean training reference, the network can learn to preserve some of that noise because it is treated as part of the wanted signal. The next step will therefore be to create a much better training dataset using genuinely clean speech recordings, ideally from several different speakers, together with a wider variety of real receiver noise. I intend to retain the existing neural architecture initially so that improvements from better training data can be evaluated independently. There is also potential to extend the system to other receiving modes, including AM and music, while retaining the existing 8 kHz neural processing engine. Final Thoughts RadioClear AI represents a significant step forward in my work on speech noise reduction for SDR Console. The most interesting aspect is not simply that it uses artificial intelligence, but how conventional DSP, recurrent neural processing and complex temporal filtering work together . By combining an adaptive noise estimator, speech-aware spectral processing and a neural network capable of exploiting relationships between consecutive audio frames, the system can perform noise reduction that would be difficult to achieve using conventional spectral attenuation alone. The aim has always been straightforward: make weak radio signals easier and more pleasant to listen to, without destroying the speech we are trying to recover. The initial results suggest that this approach has considerable potential, and I look forward to seeing how much further it can be improved with better training recordings. RadioClear AI is still evolving, but it is already producing some of the best weak-signal speech noise reduction I have achieved in SDR Console.
By Simon Brown • October 9, 2026
Can We Build a Better SSB Demodulator?
By Simon Brown • October 9, 2026
The Future of SDR Software
By Simon Brown • September 14, 2026
History
By Simon Brown • September 14, 2026
SDR Television v1.1.6 September 14th, 2026. To avoid confusion with the test versions of 1.1.5, this kit is now 1.1.6. Receiver Improved Gardner timing recovery. Improved Sum-product decoding. Redesigned soft decoder. Redesigned RRC matched filter. Note: this kit should be able to gain a dB or so sensitivity when detecting the frame header. v1.1.6 will have even better frame detection, hence better weak signal decoding. LDPS Settings, important! Open this page, select Defaults . There is no need to adjust the Sum-product optons, these options are only for development and may be hidden in future kits. Transmit Provider changed from SDR Television to SDR TV, some receivers only display a maximum of 18 characters in the provider field. Downloads are at the bottom of this page.
By Simon Brown • September 14, 2026
Improving DVB-S2 PLHEADER Detection at Low SNR Reliable detection of the DVB-S2 Physical Layer Header (PLHEADER) is one of the first challenges faced by a DVB-S2 receiver. Before the receiver can decode the payload, it must determine where a physical-layer frame begins, establish carrier phase and frequency sufficiently accurately, and decode the signalling contained in the PLS code. This becomes particularly interesting at very low SNR. I have been comparing two approaches: A traditional differential SOF/PLS detector. A new coherent, maximum-likelihood-oriented PLHEADER detector designed to exploit substantially more of the information contained in the DVB-S2 header. Both methods are trying to answer essentially the same question: At what symbol does the DVB-S2 PLHEADER begin, and what carrier frequency and phase best explain the received 90-symbol header? The difference is how much of the available information they use to answer that question. The full PDF is here .
By Simon Brown • August 27, 2026
August 27th, 2026 Default Audio Device When changing the default audio device selection in Windows, SDR Console was following the change but not reapplying the latest volume change. Example: I start playback, adjust the volume, then after a while enable my Bluetooth speaker an go outside. When the speaker is enabled SDR Console switches but didn't apply the change in volume. RDS processing AGC replaced with normalisation, Hilbert filter redesigned. Shouldn't make much difference. MIDI Startup I believe I have found the cause of the slow start of SDR Console. As part of the SDR Console startup I always call midiInGetNumDevs() to get the number of attached MIDI devices, even if the user hasn't enabled MIDI. At some stage in 2026 Microsoft introduced a bug where the first call to midiInGetNumDevs() after starting the computer results in blocking all asynchronous activity if there are no MIDI devices connected. If there are MIDI devices connected then it returns after ~100ms. I now only call midiInGetNumDevs() on startup if there are user definitions. Some programs are experiencing even worse behaviour. There should be a Windows update soon with a fix, but for now the kit below should resolve this problem in 99% of cases. Downloads Download beta kits here .